-20%

Telugu-English Sentiment and Emotion Analysis

0 Orders 0 Wish listed

₹4,999.00

Qty
Total price:
  ₹4,999.00

Detail Description

1. Abstract

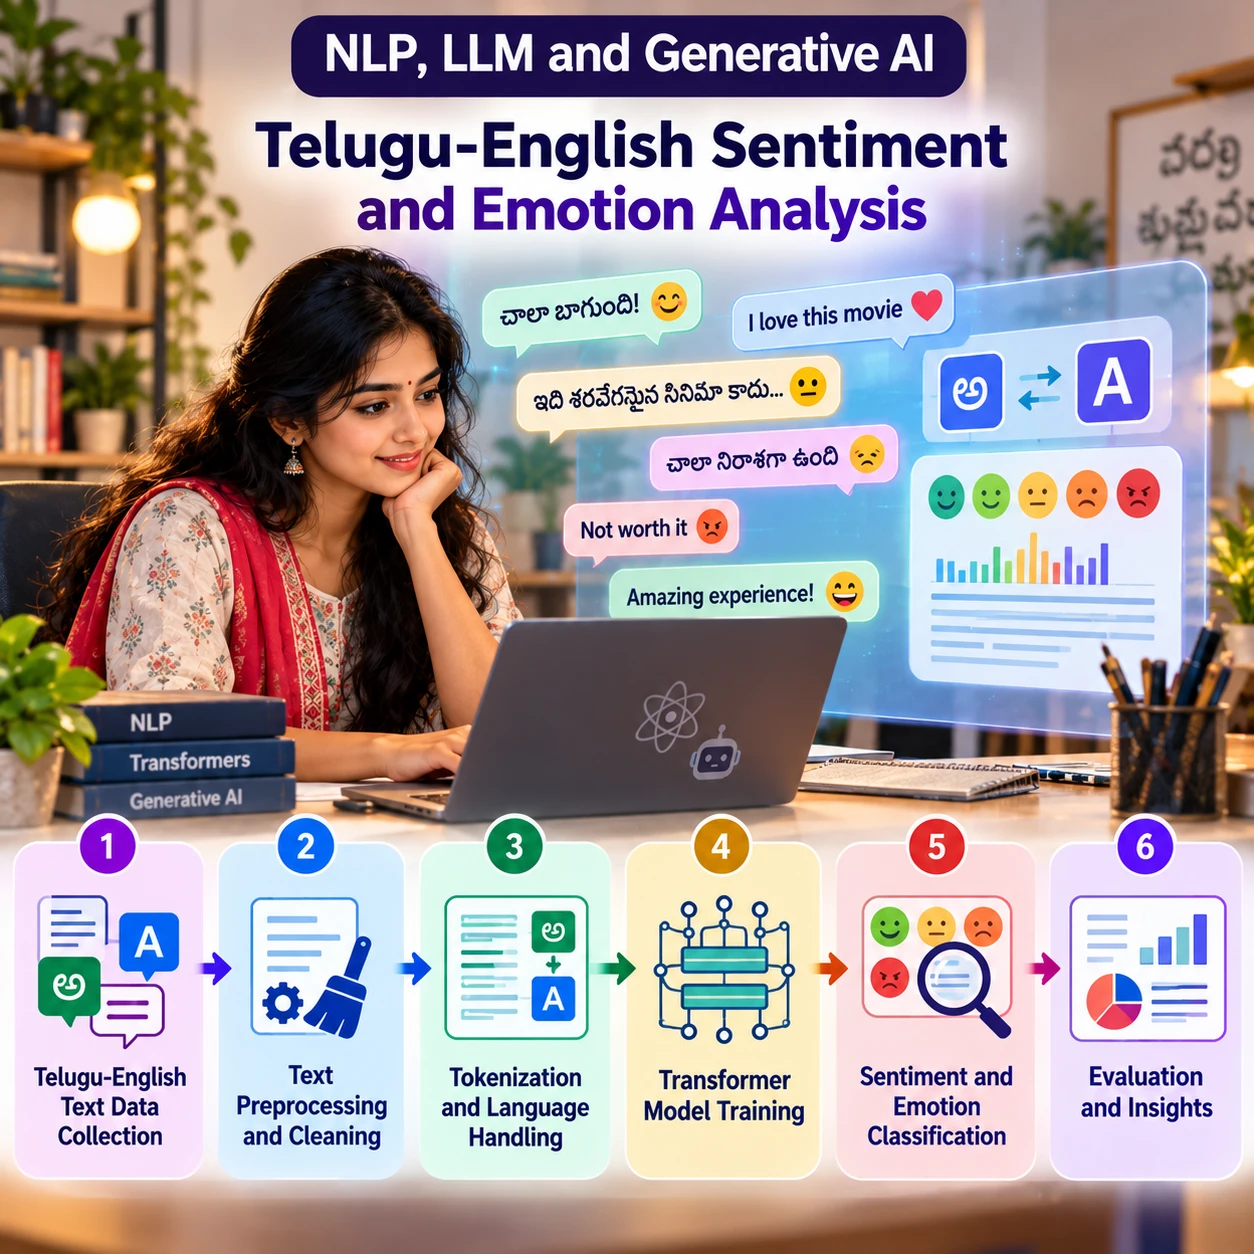
Telugu-English Sentiment and Emotion Analysis is a Natural Language Processing (NLP) project designed to analyze text written in Telugu, English, and mixed Telugu-English (code-mixed) languages. People frequently use both languages in social media posts, online reviews, comments, and digital conversations. Traditional sentiment analysis systems may struggle to interpret code-mixed text, transliterated Telugu words, and context-dependent expressions. This project uses machine learning and transformer-based language models to classify text into sentiment categories such as positive, negative, and neutral, while also identifying emotions such as happiness, sadness, anger, fear, and surprise. A web-based dashboard allows users to enter text and view sentiment predictions, emotion labels, and confidence scores. The system can support social media analysis, customer feedback monitoring, and multilingual opinion mining.

2. Objectives

  1. Develop a sentiment analysis system for Telugu, English, and mixed-language text.
  2. Identify positive, negative, and neutral sentiments.
  3. Detect emotions such as happiness, sadness, anger, fear, and surprise.
  4. Handle Telugu-English code-mixed text and transliterated Telugu.
  5. Apply NLP and transformer-based models for contextual text understanding.
  6. Analyze social media comments, reviews, and user feedback.
  7. Display prediction labels and confidence scores.
  8. Build an interactive dashboard for text analysis and visualization.

3. Existing System

Traditional sentiment analysis systems often use keyword-based methods, lexicons, or machine learning algorithms trained on single-language datasets. These methods may perform well on simple English text but struggle with Telugu-English code-mixing, spelling variations, transliteration, slang, and expressions whose meanings depend on context.

Disadvantages of the Existing System

  1. Limited support for Telugu-English code-mixed text.
  2. Difficulty interpreting Telugu written using English characters.
  3. Challenges handling spelling variations and informal expressions.
  4. Keyword-based systems may miss sarcasm and context.
  5. Sentiment classification does not always identify specific emotions.
  6. Limited labeled datasets may affect model performance.

4. Proposed System

The proposed system combines NLP preprocessing with machine learning or multilingual transformer models to analyze Telugu, English, and code-mixed text. The system processes the user's input, extracts contextual language features, and predicts sentiment and emotion categories.

Models such as multilingual BERT (mBERT), XLM-RoBERTa, or a suitable Indic language model can be evaluated. A dashboard presents the original text, predicted sentiment, detected emotion, and confidence scores.

Key Features

  1. Telugu, English, and code-mixed text analysis.
  2. Positive, negative, and neutral sentiment classification.
  3. Emotion detection, including happiness, sadness, anger, fear, and surprise.
  4. Support for informal and transliterated text when represented in training data.
  5. Confidence scores and visual summaries.
  6. Batch analysis of comments or reviews.
  7. Interactive web interface.
  8. Optional sentiment trend analysis for uploaded datasets.

Note: Emotion and sentiment labels are model predictions, not definitive measurements of a person's feelings. Accuracy depends on the quality and language coverage of the training data.

5. Implementation Procedure

  1. Dataset Collection: Collect labeled Telugu, English, and Telugu-English code-mixed text from suitable research datasets or appropriately authorized sources.
  2. Data Labeling: Assign sentiment labels and, where available, emotion labels to the text samples.
  3. Data Cleaning: Remove irrelevant formatting, handle missing values, and normalize text while preserving meaningful language features.
  4. Language Handling: Identify the language or code-mixed nature of each sample and account for Telugu script and Romanized Telugu.
  5. Text Preprocessing: Apply tokenization and model-specific preprocessing without removing important sentiment-bearing words.
  6. Model Selection: Choose a multilingual transformer such as mBERT or XLM-RoBERTa, or a suitable Indic language model.
  7. Sentiment Model Training: Fine-tune a classifier to predict positive, negative, and neutral sentiment.
  8. Emotion Model Training: Train a separate emotion classifier or use a multi-task model if suitable emotion-labeled data is available.
  9. Prediction Module: Process user input and generate sentiment and emotion predictions with confidence scores.
  10. Dashboard Development: Build a web application using Streamlit or Flask.
  11. Visualization: Display sentiment distributions, emotion summaries, and results for individual text samples.
  12. Performance Evaluation: Measure accuracy, precision, recall, macro F1-score, and confusion matrix results.
  13. Language-Wise Testing: Evaluate performance separately on Telugu-script, English, and code-mixed text.
  14. Final Testing: Test spelling variations, informal expressions, sarcasm, and unseen text to understand model limitations.

6. Software Requirements

  1. Programming Language: Python
  2. Development Environment: VS Code, PyCharm, or Jupyter Notebook
  3. NLP Libraries: Hugging Face Transformers, Tokenizers
  4. Deep Learning Framework: PyTorch or TensorFlow
  5. Language Models: mBERT, XLM-RoBERTa, or a suitable Indic language model
  6. Data Processing: Pandas, NumPy
  7. Machine Learning: Scikit-learn
  8. Visualization: Matplotlib, Seaborn, Plotly
  9. Dashboard: Streamlit or Flask
  10. Dataset: Telugu sentiment, English sentiment, and Telugu-English code-mixed text datasets
  11. Operating System: Windows or Linux

7. Hardware Requirements

  1. Processor: Intel Core i5 or equivalent and above
  2. RAM: Minimum 8 GB; 16 GB recommended
  3. Storage: At least 15–20 GB of free space, depending on dataset and model size
  4. GPU: NVIDIA GPU recommended for faster transformer fine-tuning
  5. VRAM: 6–8 GB or more recommended for smaller experiments, depending on model configuration
  6. Internet Connection: Required for downloading datasets, libraries, and pretrained models

8. Advantages of the Project

  1. Supports sentiment analysis across Telugu and English.
  2. Addresses code-mixed language commonly used in digital conversations.
  3. Identifies both sentiment polarity and specific emotion categories.
  4. Helps analyze customer reviews and social media feedback.
  5. Uses contextual language models rather than relying only on keywords.
  6. Provides visual summaries for large collections of text.
  7. Can be extended to multilingual customer-support analytics.
  8. Supports research into Indian-language NLP and code-mixed language understanding.


No review given yet!

Fast Delivery all across the country
Safe Payment
7 Days Return Policy
100% Authentic Products

You may also like

View all

LLM Safety, Toxicity and Prompt-Injection Detection

₹4,999.00

Long-Document Information Extraction using LLMs

₹4,999.00

AI Meeting Transcription and Action-Item Generator

₹4,999.00

Explainable Automatic Essay Evaluation

₹4,999.00

LLM-Based Synthetic Dataset Generation

₹4,999.00

Telugu-English Sentiment and Emotion Analysis
₹4,999.00 ₹0.00
₹4,999.00
4999