-20%

Personalized Treatment Recommendation

0 Orders 0 Wish listed

₹4,999.00

Qty
Total price:
  ₹4,999.00

Detail Description

1. Abstract

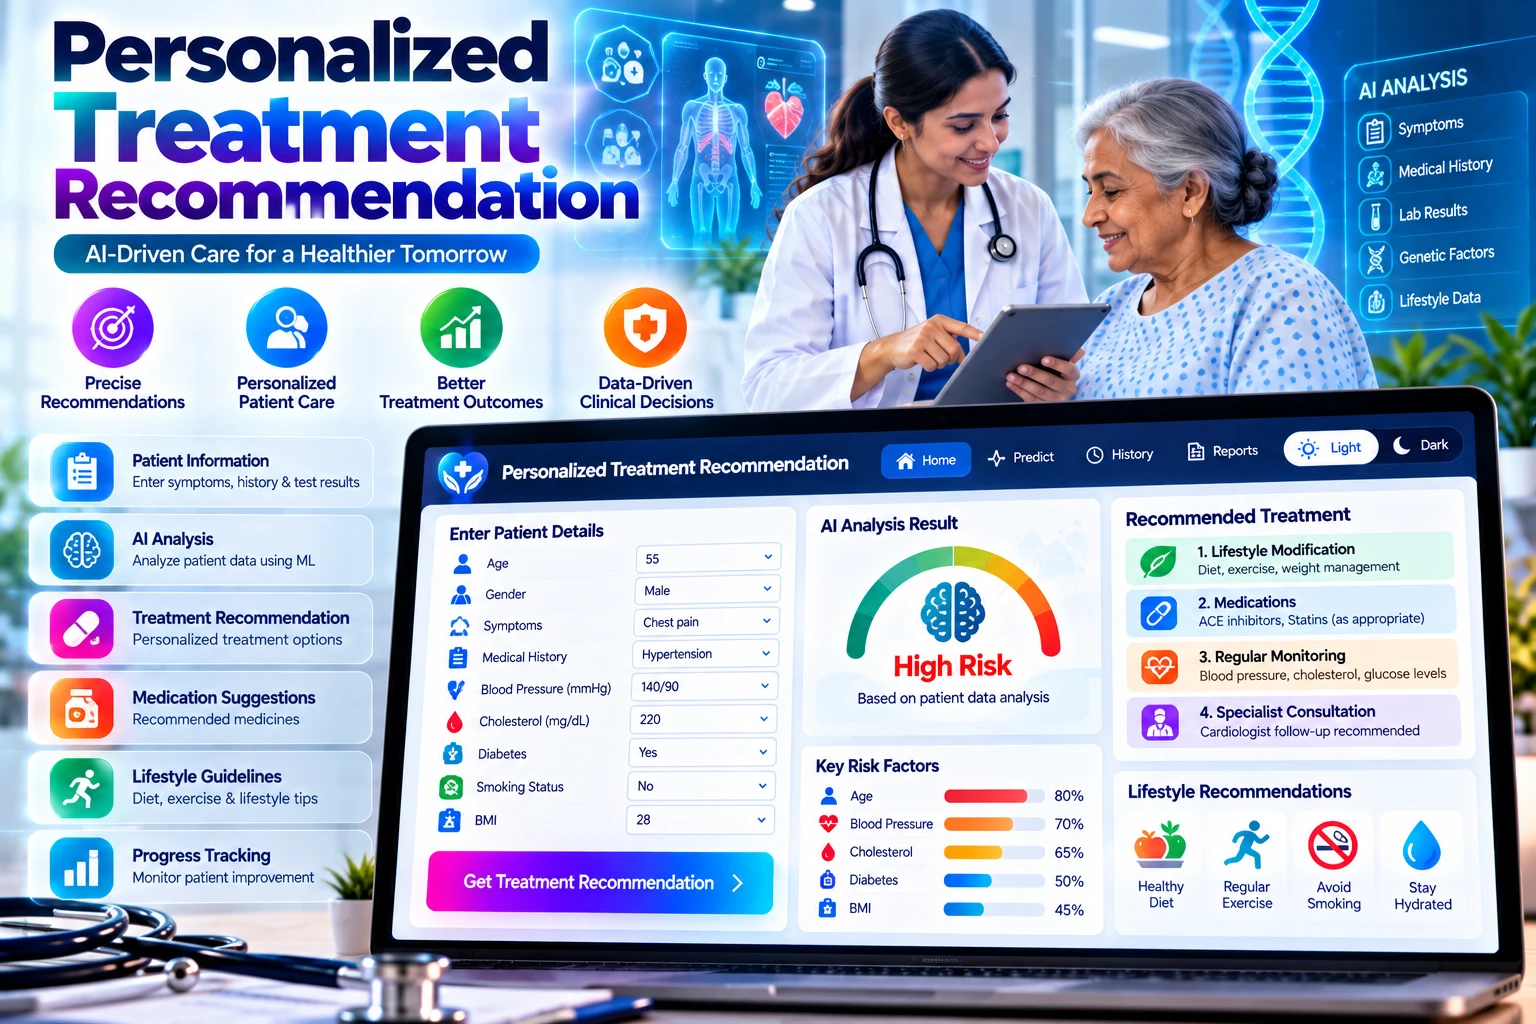
Personalized Treatment Recommendation is a machine learning-based healthcare application designed to provide data-driven treatment suggestions based on patient-specific information. The system analyzes relevant factors such as patient age, gender, symptoms, medical history, diagnosis, laboratory results, existing conditions, medications, and other clinical parameters. A machine learning model is trained using appropriate historical healthcare data to identify patterns between patient characteristics and treatment outcomes. Based on the provided patient information, the system generates a personalized recommendation or treatment category for further clinical consideration. The proposed system aims to support healthcare professionals in organizing patient information and exploring data-driven options. It is intended as a clinical decision-support and research system, not a replacement for a qualified healthcare professional or independent medical advice.

2. Objectives

  1. To develop a machine learning-based personalized treatment recommendation system.
  2. To analyze patient-specific clinical and demographic information.
  3. To identify patterns between patient characteristics and treatment outcomes.
  4. To preprocess and prepare healthcare data for machine learning.
  5. To generate patient-specific treatment recommendations or treatment categories.
  6. To provide a simple interface for entering patient information.
  7. To support healthcare professionals with data-driven decision support.
  8. To evaluate the recommendation model using suitable performance metrics.
  9. To improve personalization of healthcare data analysis.

3. Existing System

In the existing system, treatment decisions are primarily made by qualified healthcare professionals based on patient history, symptoms, diagnostic results, medical guidelines, clinical experience, and individual patient conditions. Healthcare professionals manually review multiple sources of patient information before determining an appropriate treatment approach.

Limitations of the Existing System

  1. Reviewing large amounts of patient information can be time-consuming.
  2. Patient information may be distributed across multiple records.
  3. Identifying patterns across large historical datasets can be difficult manually.
  4. Treatment decisions require careful consideration of multiple clinical factors.
  5. Conventional systems may provide limited personalization based on historical treatment outcomes.
  6. Large-scale healthcare data is difficult to analyze without computational assistance.

4. Proposed System

The proposed Personalized Treatment Recommendation System uses machine learning techniques to analyze patient information and identify treatment patterns from historical healthcare data. The system preprocesses patient records by handling missing values, removing inconsistencies, encoding categorical attributes, and transforming numerical features when required.

Depending on the dataset, algorithms such as Decision Tree, Random Forest, Logistic Regression, K-Nearest Neighbors (KNN), Support Vector Machine (SVM), or recommendation-based approaches can be used. The model analyzes patient characteristics and generates a suitable treatment category or recommendation based on learned patterns.

A user-friendly interface can be developed using Streamlit or Flask, allowing authorized users to enter patient information and view the model-generated recommendation along with relevant patient factors.

5. Implementation Procedure

Step 1: Dataset Collection

Collect an appropriate and ethically sourced healthcare dataset containing patient characteristics, diagnoses, treatments, and relevant outcomes.

Step 2: Data Preprocessing

  1. Load the dataset using Python.
  2. Identify missing and invalid values.
  3. Handle missing values appropriately.
  4. Remove duplicate or inconsistent records.
  5. Encode categorical variables.
  6. Normalize or scale numerical features when required.

Step 3: Exploratory Data Analysis

Analyze relationships between patient characteristics, diagnoses, treatments, and outcomes.

Step 4: Feature Selection

Select relevant patient and clinical features that contribute to treatment recommendation.

Step 5: Dataset Splitting

Divide the dataset into training and testing subsets, for example:

  1. Training Data: 80%
  2. Testing Data: 20%

Step 6: Model Training

Train suitable machine learning or recommendation models using the prepared dataset.

Step 7: Model Evaluation

Evaluate the model using appropriate metrics such as:

  1. Accuracy
  2. Precision
  3. Recall
  4. F1-score
  5. Confusion Matrix
  6. Top-K Recommendation Accuracy, where applicable

Step 8: Model Selection

Select a suitable model based on overall performance and the requirements of the intended application.

Step 9: Application Development

Develop a user-friendly interface using Streamlit or Flask for entering patient information.

Step 10: Recommendation Generation

Process the patient information through the trained model and generate the corresponding recommendation or treatment category.

Step 11: Testing

Test the application using representative test cases and verify that the recommendation workflow operates correctly.

Step 12: Deployment

Deploy the application in a controlled environment with appropriate security, privacy, access control, and clinical oversight.

6. Software Requirements

RequirementRecommended Software
Operating SystemWindows 10/11, Linux, or macOS
Programming LanguagePython 3.x
IDEVS Code / PyCharm / Jupyter Notebook
Data ProcessingPandas, NumPy
Machine LearningScikit-learn
Data VisualizationMatplotlib, Seaborn
Web FrameworkStreamlit or Flask
Model StorageJoblib / Pickle
DatabaseSQLite/MySQL (Optional)
BrowserGoogle Chrome / Microsoft Edge
Version ControlGit/GitHub

7. Hardware Requirements

ComponentMinimum Requirement
ProcessorIntel Core i3 or equivalent
RAM4 GB minimum; 8 GB recommended
Storage10 GB available space
Display1366 × 768 resolution or higher
KeyboardStandard keyboard
MouseStandard mouse
InternetRequired for online resources/deployment
GPUNot required for basic machine learning models

8. Advantages of the Project

  1. Provides personalized, data-driven treatment recommendations for research and decision support.
  2. Analyzes multiple patient parameters simultaneously.
  3. Helps organize complex patient information.
  4. Uses historical healthcare data to identify treatment patterns.
  5. Provides a simple and user-friendly interface.
  6. Can support healthcare professionals during preliminary analysis.
  7. Allows comparison of different machine learning approaches.
  8. Can be extended with additional clinical features and treatment outcomes.
  9. Can incorporate explainable AI to show factors influencing recommendations.
  10. Can be developed as a web-based healthcare application.
  11. Demonstrates the practical application of machine learning in personalized healthcare.


No review given yet!

Fast Delivery all across the country
Safe Payment
7 Days Return Policy
100% Authentic Products

You may also like

View all

Edge–Cloud AI Inference System

₹4,999.00

Federated Learning Platform

₹4,999.00

End-to-End MLOps Pipeline

₹4,999.00

Model Monitoring and Drift Detection

₹4,999.00

Automated ML Model Deployment Platform

₹4,999.00

Personalized Treatment Recommendation
₹4,999.00 ₹0.00
₹4,999.00
4999